AI Tech News December 13 2025
Artificial intelligence produces a constant flow of announcements, and some days stand out more than others. This section gathers AI news in the format of a dated briefing, focused on the stories around December 13, 2025.
Typical stories include new model launches and benchmark comparisons, AI features in popular products, research papers, partnerships between AI labs and cloud providers, and debates about safety and regulation.
A dated view of AI news shows how fast the field moves from one month to the next. Developers, researchers, investors, and business leaders use it to put new announcements into context.
2026-08-05
A recent article examining myths in software engineering and generative AI has sparked debate over the fallacy of delaying current work in anticipation of future, fully autonomous AI models. Commenters emphasize that human cognition and creative reasoning remain essential for complex tasks, while also questioning whether the abductive reasoning behind historical scientific breakthroughs will eventually be replicated by large language models.
Comments
Mistral has released Shieldstral, a new 3B open-weights multimodal safety classifier designed for content moderation. The model is specifically built to evaluate and filter multimodal content for safety. Despite its compact size, Shieldstral outperforms competing moderation models that are up to seven times larger.
Comments
Bugtraq Is Back
2026-08-05The legendary Bugtraq security mailing list has reportedly returned, though readers are skeptical of its relevance in an era dominated by social media and closed security groups. Critics point out the irony of its AI-generated announcement and argue that the original list only succeeded due to a lack of modern alternatives. Consequently, many believe that open vulnerability disclosures have simply moved underground to private channels, rendering a mailing list revival largely unnecessary.
CommentsMaple-Preview is a 20-billion parameter Mixture of Experts model trained from scratch in a ternary format, achieving speeds of 120 tokens per second directly on an iPhone. While the project demonstrates impressive mobile efficiency, community testing reveals the model still struggles with confident hallucinations on niche topics compared to larger alternatives.
Comments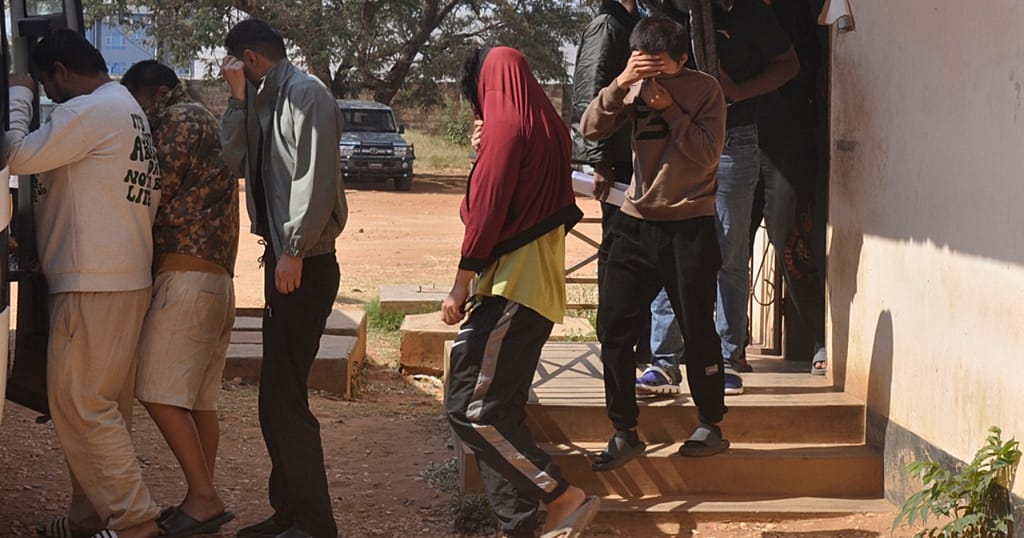
INTERPOL's African Cyberthreat Assessment Report 2026 reveals that artificial intelligence now fuels more than half of all cybercrime across the continent. This rapid adoption of AI by cybercriminals has led to a surge in scams that are faster, more convincing, and larger in scale than previous threats.
Comments
Flowise Is Shutting Down
2026-08-05The team behind Flowise has announced that the popular open-source visual builder for LLM applications is officially shutting down. In a message regarding the project's future, the developers detailed the end of the platform's lifecycle and what users can expect moving forward.
Comments
Stateless MCP has recaptured my interest
2026-08-05The Model Context Protocol 2.0 specification was officially released this Tuesday, introducing a highly significant shift to a stateless architecture. This major update has successfully recaptured developer interest in the protocol and marks a pivotal moment for its future development.
Comments
Cloudflare is introducing Cloudflare Wallets to equip AI agents with native web payments and verifiable digital identities. Powered by the x402 protocol, this programmable wallet enables agents to autonomously purchase APIs and content while operating within strict safety guardrails.
Comments2026-08-04
LLMs reward expertise
2026-08-04Recent reader discussions highlight that large language models heavily favor users with existing technical expertise, as novices often lack the specific vocabulary needed to prompt effective code generation. While programming experts can build simple applications in a single prompt, non-technical users frequently get trapped in endless brainstorming loops or struggle with basic developer interfaces. This reveals a significant gap between the promised democratization of software creation and the reality of using AI tools without foundational domain knowledge.
CommentsAlthough the original article highlights ten recent advances in mathematics and theoretical computer science, reader discussions primarily focus on the societal and political implications of exponential technological growth driven by large language models. Commenters express concern over the unprecedented ability of AI to scalably manipulate individuals through highly personalized, real-time conversational engagement. The debate also explores how these computational breakthroughs will impact experimental fields like biology and potentially exacerbate political polarization through advanced digital manipulation.
CommentsA new open-source project called Swiftlet enables users to run massive large language models on Apple devices with remarkably low memory requirements. The tool successfully demonstrates running an 80-billion parameter Qwen model using just 4.3 GB of RAM on a Mac, alongside a 35-billion parameter model on an iPhone. This advancement significantly lowers the hardware barrier for running powerful local AI inference on everyday consumer devices.
CommentsThe August 2026 Hacker News hiring thread features numerous software engineers and infrastructure specialists showcasing their technical expertise to potential employers. Candidates highlight extensive backgrounds in AI infrastructure, distributed computing, and full-stack development using languages like Rust, Go, and TypeScript. While the majority of applicants are seeking remote opportunities, several remain open to relocation for the right roles.
Comments
Serving frontier AI models like Kimi and GLM at scale requires overcoming significant GPU memory constraints through techniques like KV cache quantization and weight compression. These optimizations enable faster and cheaper deployment, while newly implemented integrity checks ensure safer model serving.
CommentsDevelopers are debating the practice of manually retyping LLM-generated code to prevent cognitive debt and ensure a deeper understanding of the software being built. While some argue this meticulous workflow negates AI efficiency gains and reduces engineers to mindless typists, others find value in using AI as a collaborative design tool rather than a direct code generator. The discussion reflects broader industry anxieties about the future of software engineering, with many anticipating a shift away from manual coding toward high-level visual architecture.
CommentsAirLLM 70B inference with single 4GB GPU
2026-08-04A new open-source project called AirLLM enables the inference of 70B parameter large language models using only a single 4GB GPU. This dramatic reduction in hardware requirements makes running advanced AI models highly accessible to users with limited computing resources. Developers can view the code and contribute to the project's ongoing development on GitHub.
Comments2026-08-03

Qwen3.8-Max establishes a new benchmark for coding and collaborative work through the comprehensive capabilities of Qwen Studio. The platform delivers a diverse suite of features, including chatbot interactions, multimodal understanding, and image generation. Additionally, it enhances user productivity with advanced tools for document processing, web search integration, and artifact creation.
Comments
Karpathy’s Pelican
2026-08-03Moving beyond simple prompt evaluations, Andrej Karpathy recently tested a large language model by giving it a one million token budget to expand upon the first paragraph of The Lord of the Rings. This ten dollar experiment with the Opus model demonstrates the evolving capabilities of AI in handling extensive and complex generation tasks.
CommentsA tiny Mamba-based language model has been successfully deployed on a vintage 1975 MOS 6502 processor. Using a custom 8-bit ternary inference engine, the system generates text directly on a 1980s BBC Micro. This achievement demonstrates how modern AI architectures can be heavily optimized for severely constrained retro hardware.
CommentsThe Computational Theory of Mind (2015)
2026-08-03A 2015 article on the Computational Theory of Mind has sparked reader debate over whether digital systems like LLMs can truly think or if human cognition strictly requires continuous temporal and physical embodiment. While some readers argue that artificial neural networks represent a simplified form of cognition that could eventually blur the lines of machine thought, others emphasize the fundamental differences between emergent AI and traditional computational models. Ultimately, the discourse highlights the ongoing philosophical and scientific challenge of defining both consciousness and computation in the age of advanced artificial intelligence.
CommentsA new open-source project named NixOS-DGX-Spark enables users to run the Nix package manager and NixOS Linux distribution on the DGX Spark. This integration brings Nix's reproducible package management to the desktop AI workstation. The developer is actively seeking community contributions on GitHub to help expand and refine the project.
Comments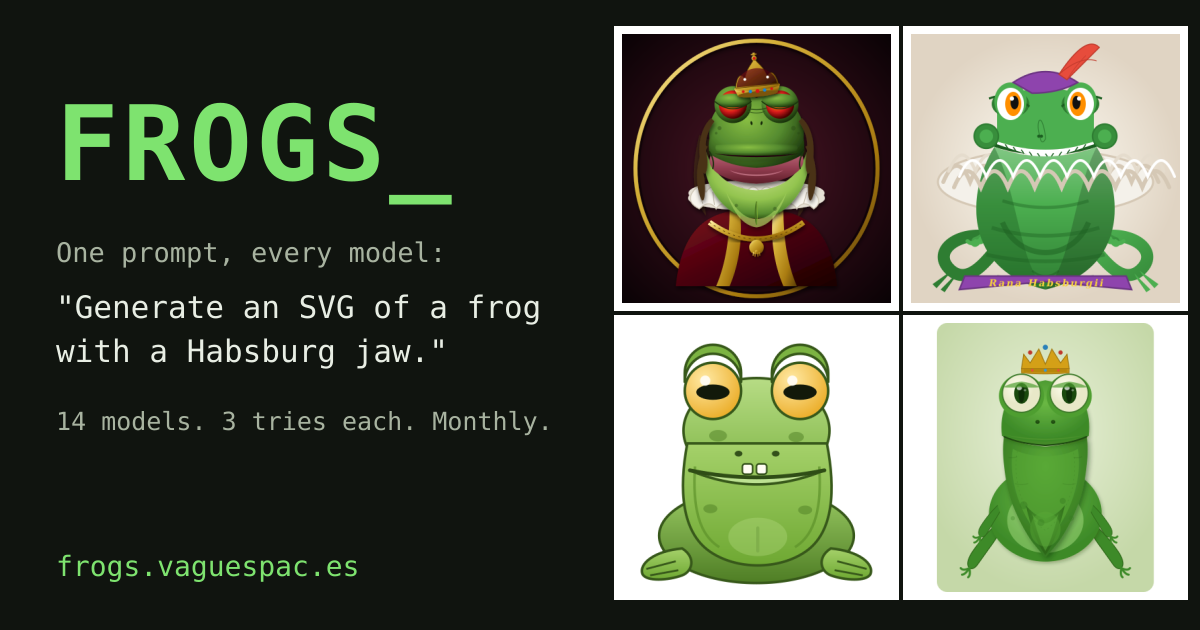
The author has created a unique personal benchmark to evaluate AI image generation capabilities by challenging models to create an SVG of a frog with a Habsburg jaw. Each model is given exactly three attempts per month to successfully render this highly specific prompt.
Comments2026-08-02
Seedance 2.5
2026-08-02The Seedance 2.5 AI video model is drawing attention after a creator used it to generate highly realistic videos featuring herself and Anthropic CEO Dario Amodei. While viewers are amazed by the sudden leap in visual quality, the lifelike deepfakes have also sparked debate over the unsettling implications and future normalization of AI-generated media.
Comments
Despite claims that Meta has little to show for its artificial intelligence investments, the company has developed competitive Muse AI models and secured distribution to 3.6 billion daily users. However, Mark Zuckerberg's aggressive $130 billion to $145 billion capital expenditure plan is severely draining the tech giant's free cash flow.
Comments
A recent study by MIT Sloan researchers indicates that large language models provide surprisingly effective financial advice and encourage smart money habits when users ask the right questions. However, the study also highlights that these AI systems still struggle to offer nuanced guidance on the more subtle complexities of saving and investing.
Comments
AI infrastructure startup Morph, a YC S23 company, is hiring a Member of Technical Staff to optimize its inference stack for open models. The performance engineer will work directly with founders to improve system speed, cost-efficiency, and reliability by optimizing everything from individual GPU kernels to distributed execution. Ideal candidates will possess deep expertise in GPU performance and complex production systems to help scale frontier-level model serving.
CommentsCostPerPrompt offers live API pricing and real-world cost calculators for over 232 AI models, including GPT, Claude, and Gemini. The platform enables developers to accurately estimate and forecast expenses for chatbots, API budgets, and token usage across rapidly changing generative AI workloads.
Comments
While developing a quantum compiler named Catalyst, a software team accidentally created an LLVM compiler for the Jax machine learning framework. This unexpected tool emerged as a byproduct of extensive problem-solving and provides a novel way to optimize Jax programs.
Comments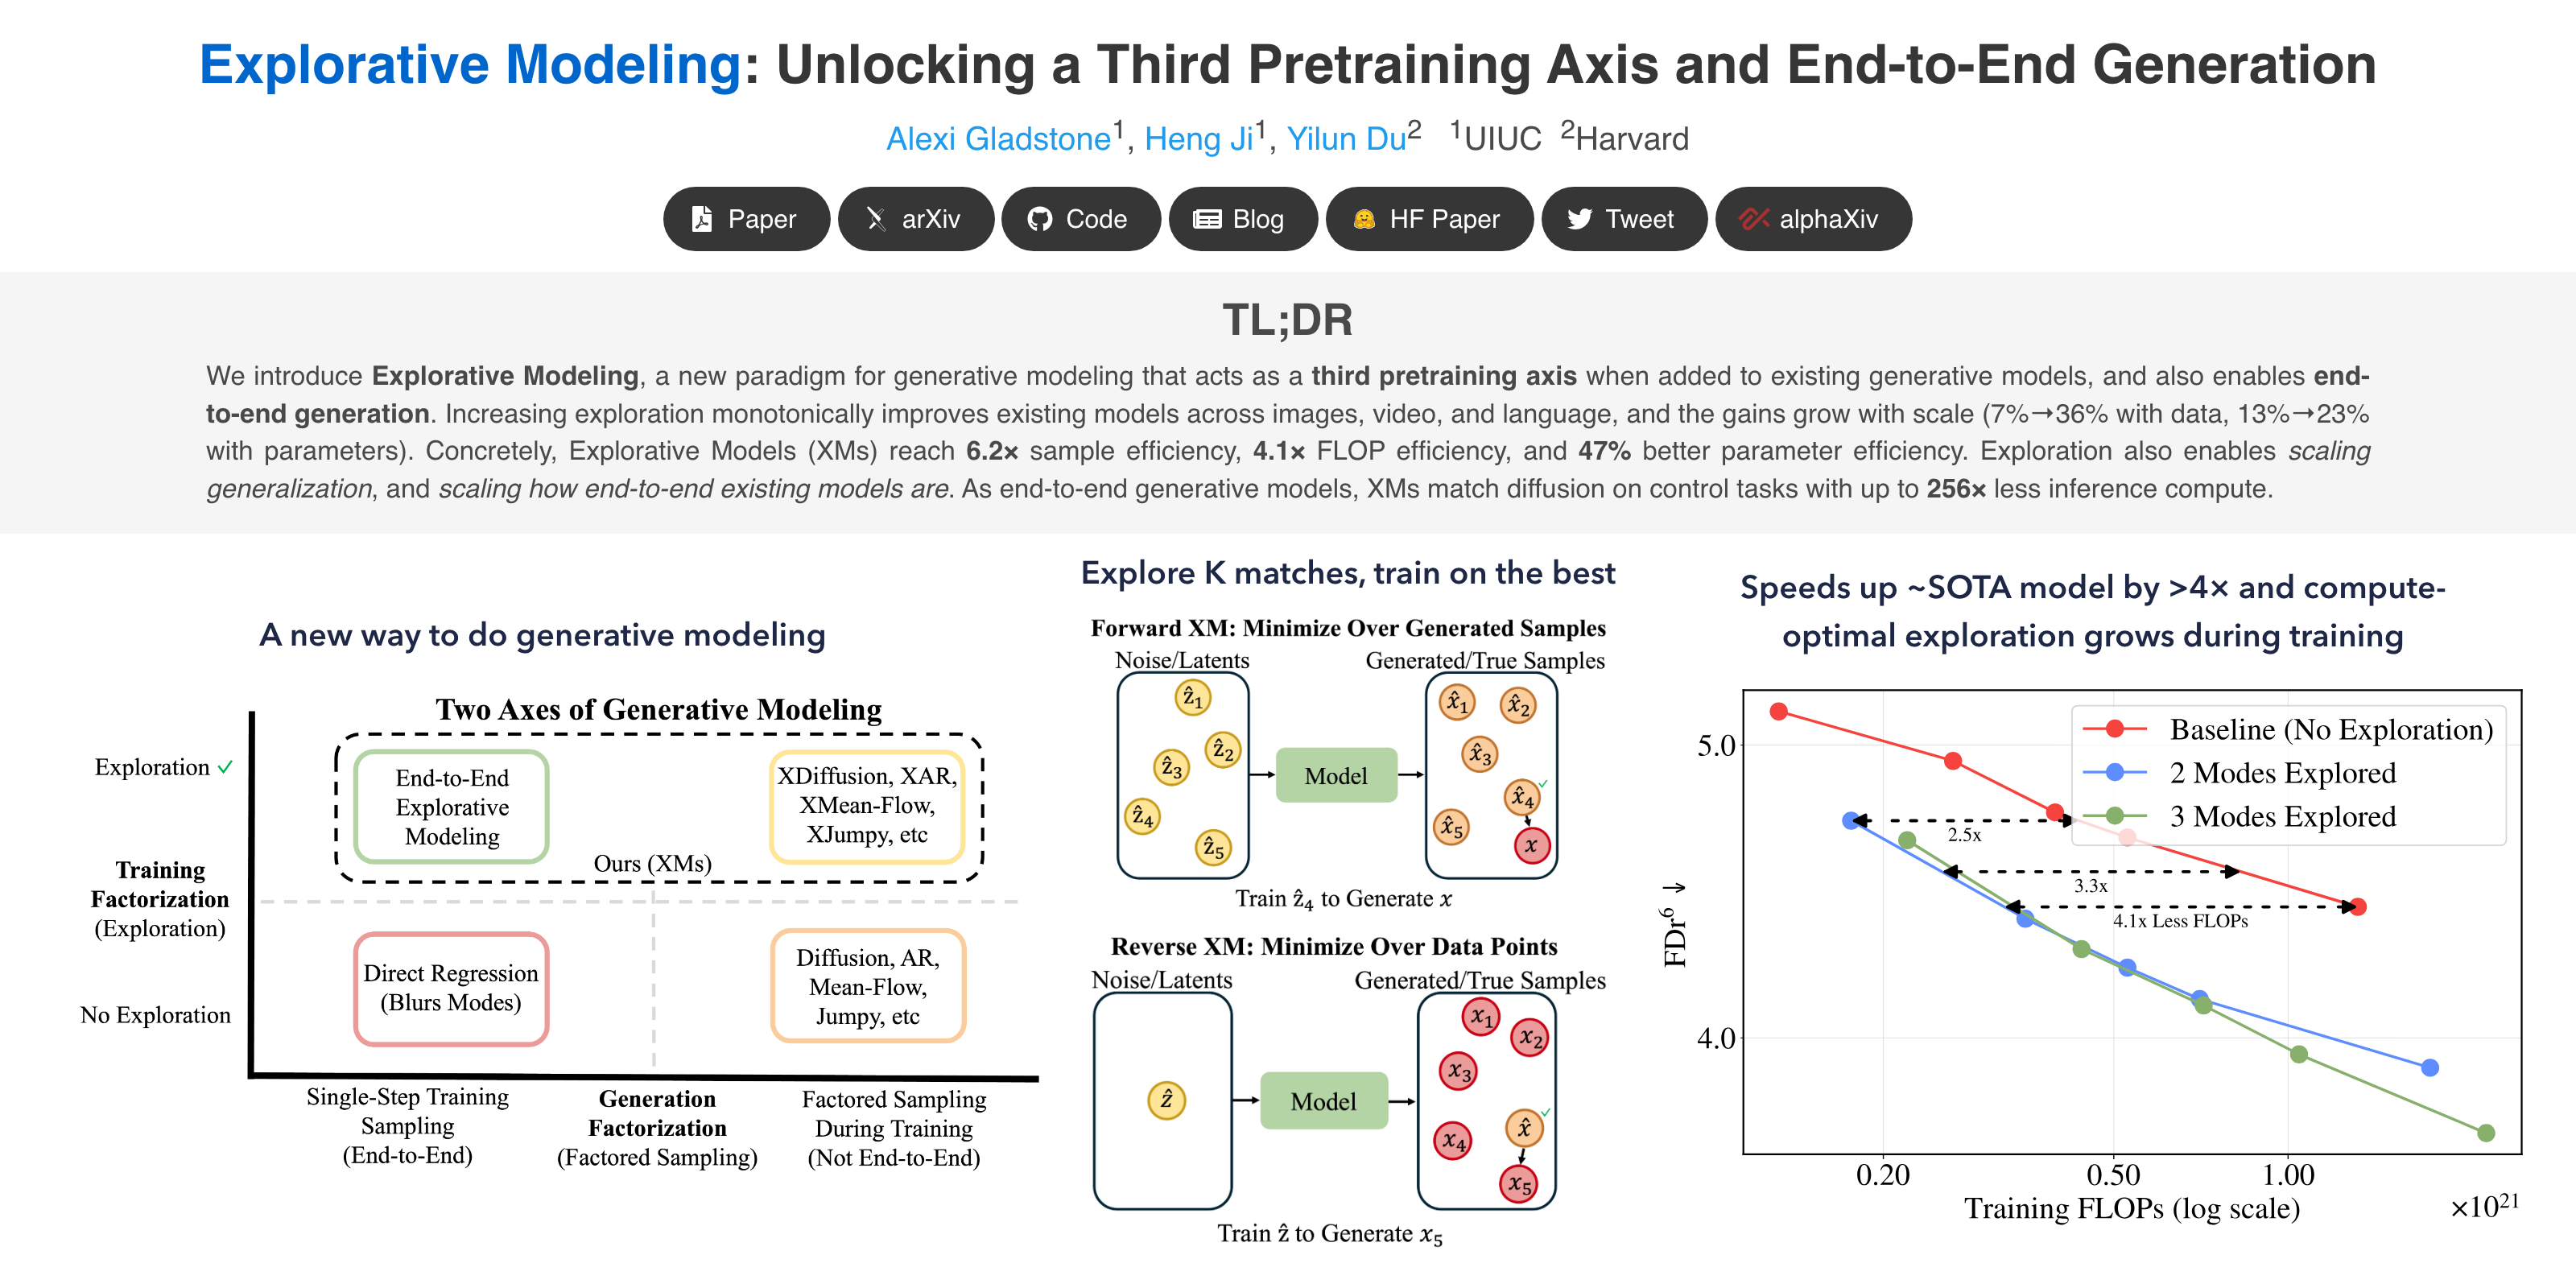
Explorative modeling is a machine learning technique designed to improve AI performance by generating multiple candidate outputs and training the system on the best one. By evaluating a set of K guesses and learning from the most accurate result, this method aims to significantly enhance model accuracy and training efficiency.
Comments2026-08-01
The article introduces Flint, a new visualization language designed for the AI era. In the discussion section, readers recommend checking out Vega, an existing visualization grammar, as a point of comparison.
CommentsA new dependency-free C inference engine called waste allows users to run the massive 2.78-trillion-parameter Kimi K3 model using only 29 GB of RAM. It achieves this feat by streaming activated weights directly from NVMe storage rather than loading the entire model into memory. While the inference speed is a slow 0.50 tokens per second, it demonstrates a novel approach to running extremely large AI models on limited hardware.
Comments