news
366
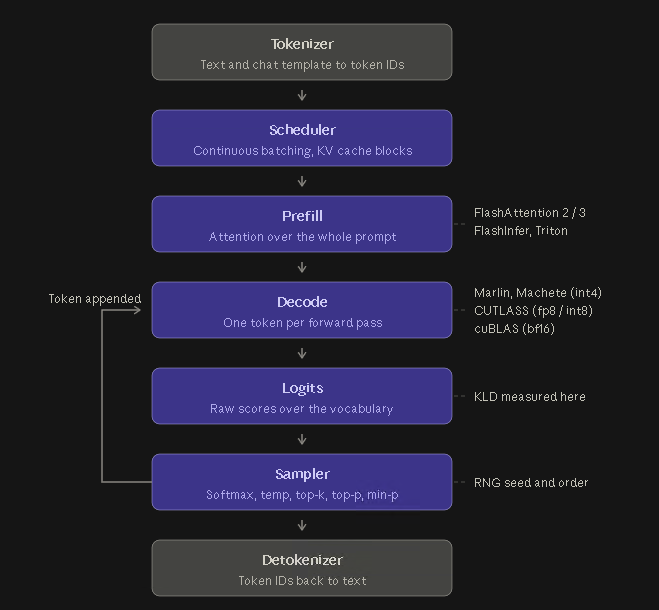
Despite immense online hype surrounding new Large Language Models, users frequently experience a massive letdown when running locally hosted, quantized versions. This article explores the technical reasons behind this performance gap, explaining why your local AI might feel significantly dumber than its full-weight or cloud-based counterparts.
Comments
0Discuss on Hacker NewsOnly full members can comment
Log in to express your opinion.
No comments yet.