news
39
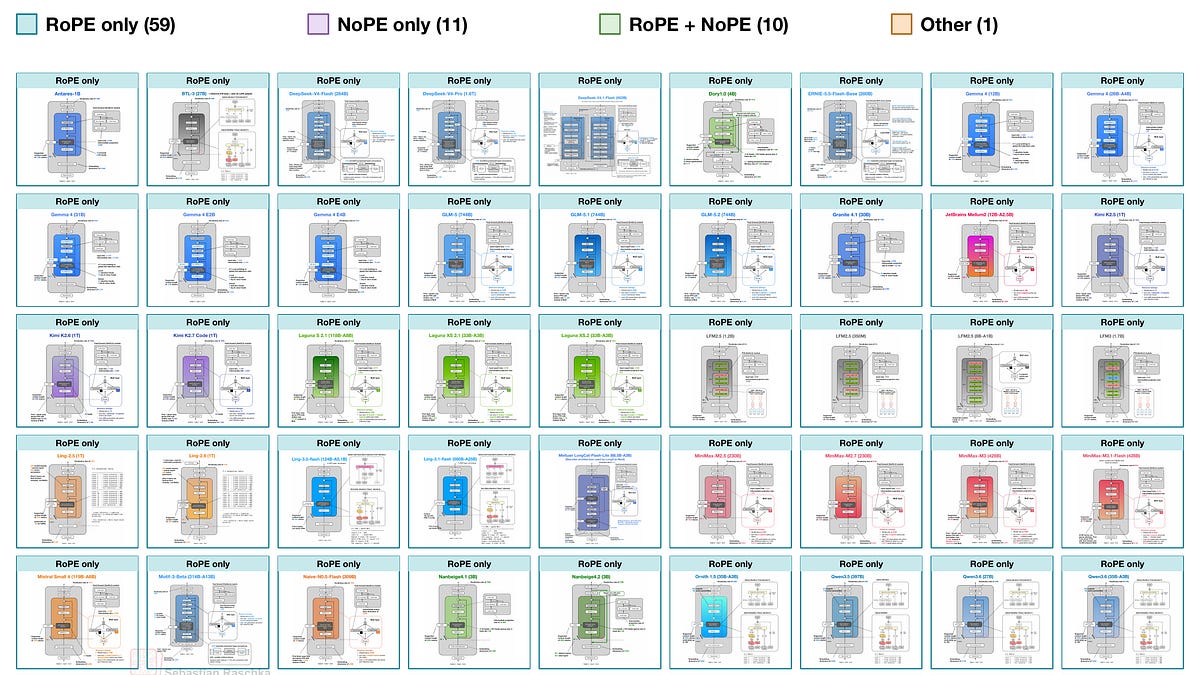
The article explains positional embeddings, which let LLMs encode where tokens appear in a sequence so attention can distinguish order and structure. It surveys common approaches—learned absolute embeddings, relative position schemes, and modern methods like rotary embeddings and ALiBi—while discussing tradeoffs around context length, extrapolation, and efficiency.
Comments
0Discuss on Hacker NewsOnly full members can comment
Log in to express your opinion.
No comments yet.