news
80
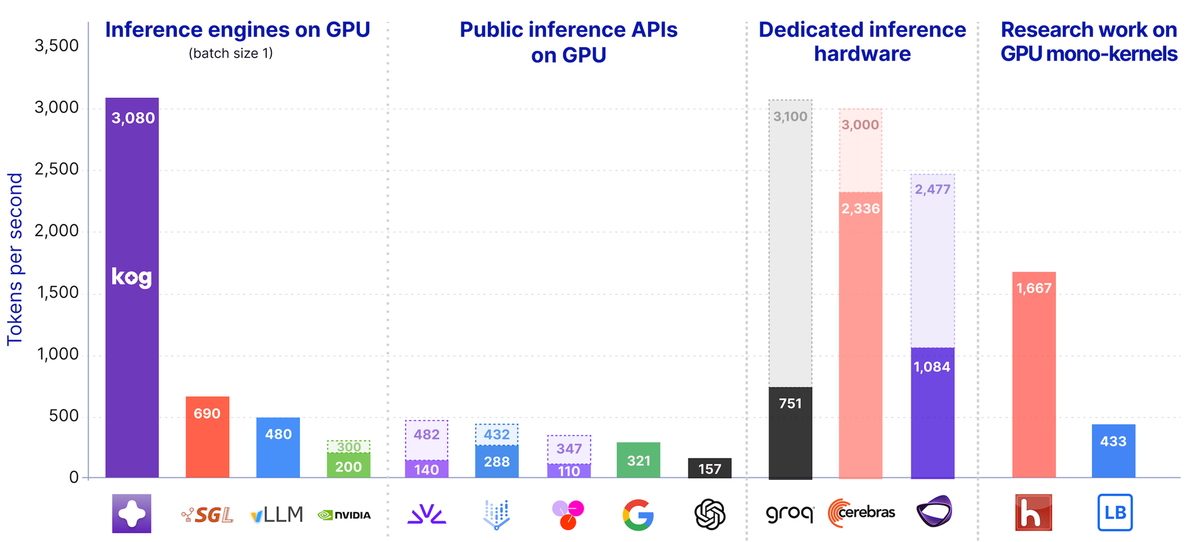
Kog AI has launched a tech preview of its Kog Inference Engine, achieving real-time inference speeds of up to 3,000 output tokens per second on AMD MI300X GPU clusters and 2,100 on NVIDIA H200 systems. The current preview runs a 2B model, with support for larger third-party mixture-of-experts models planned for the near future at similar speeds.
Comments
0Discuss on Hacker NewsOnly full members can comment
Log in to express your opinion.
No comments yet.