news
153
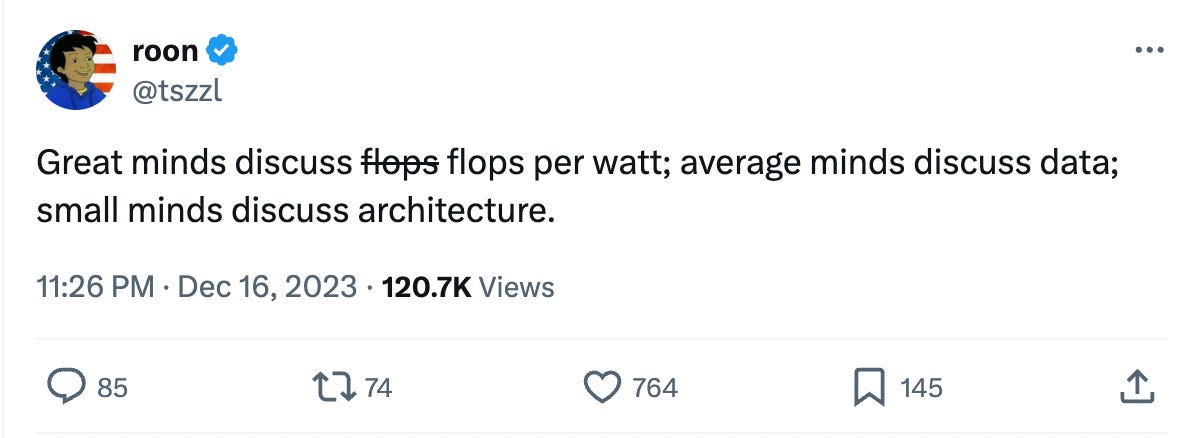
Recent findings indicate that GPU matrix multiplications, the core operation for AI workloads, execute significantly faster when processing data with predictable access patterns. This optimization minimizes memory bottlenecks and maximizes compute efficiency, ultimately delivering substantial improvements in flops per watt for large-scale machine learning models.
Comments
0Discuss on Hacker NewsOnly full members can comment
Log in to express your opinion.
No comments yet.