news
278
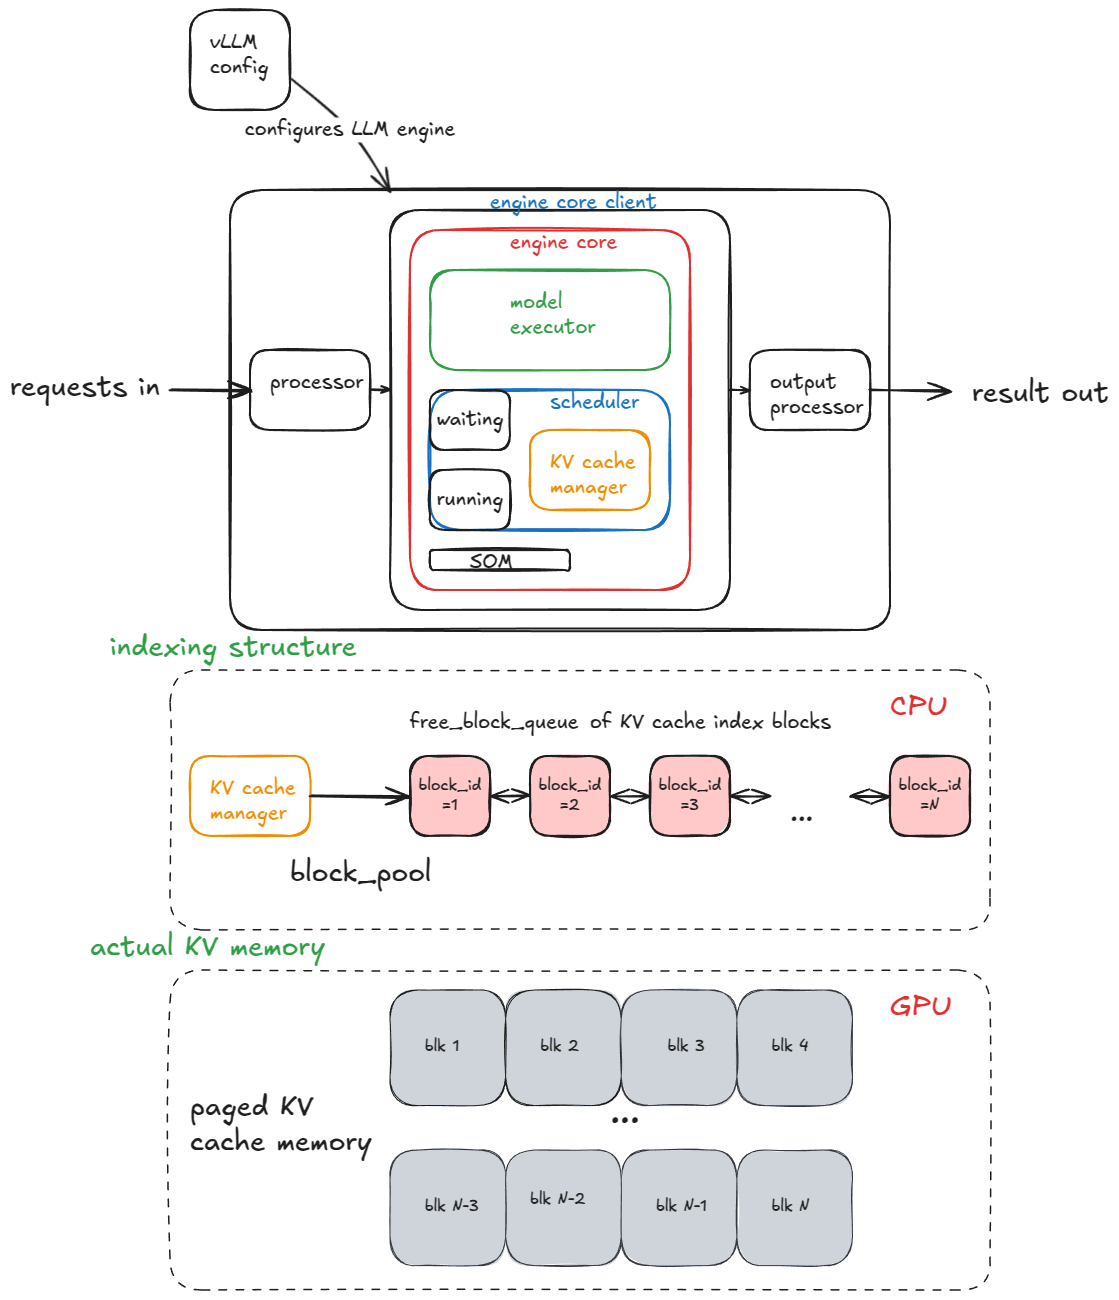
A new technical deep dive explores the internal architecture of vLLM, a high-throughput LLM inference system designed for massive scale. It breaks down core performance optimizations including paged attention, continuous batching, prefix caching, and speculative decoding. Additionally, the article examines how the platform enables dynamic serving across multi-GPU and multi-node environments.
Comments
0Discuss on Hacker NewsOnly full members can comment
Log in to express your opinion.
No comments yet.