news
139
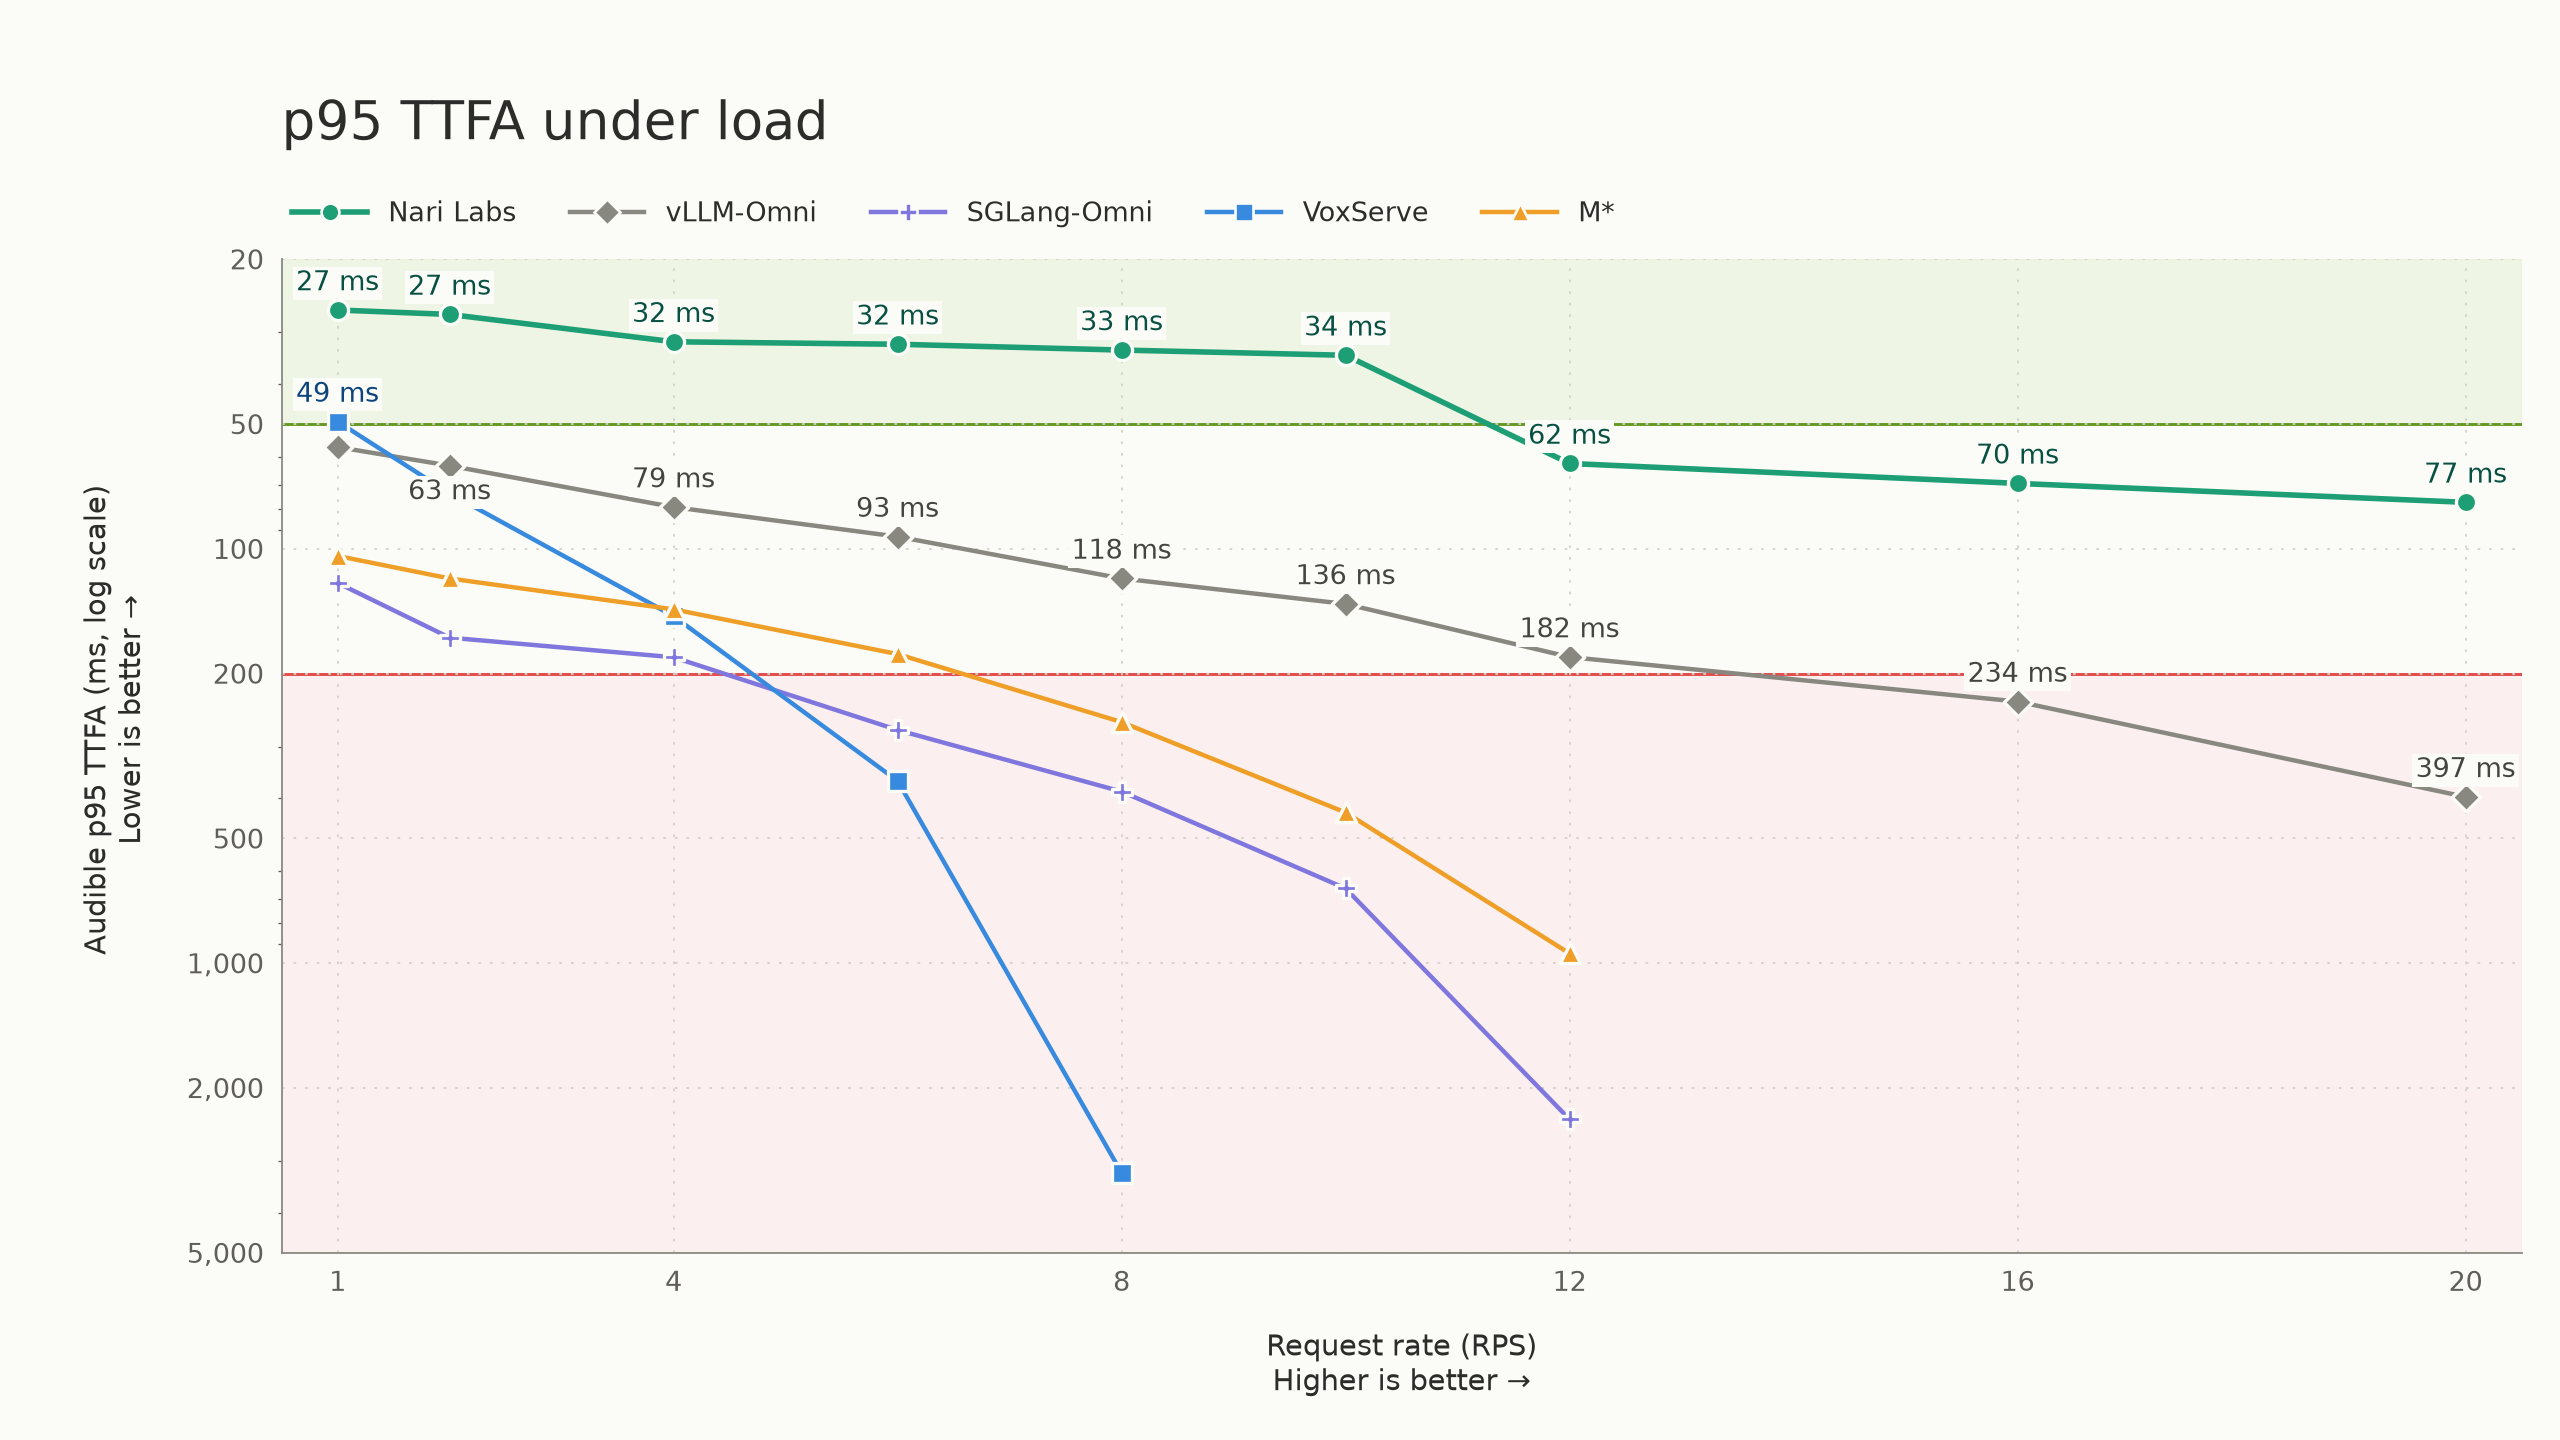
Engineers have optimized the serving infrastructure for the Qwen3-TTS model to achieve a p95 time-to-first-audio latency of under 50 milliseconds on a single H100 GPU. By processing 10 requests per second with this ultra-low response time, the optimization marks a significant step forward for real-time, high-throughput voice synthesis applications.
Comments
0Discuss on Hacker NewsOnly full members can comment
Log in to express your opinion.
No comments yet.