news
256
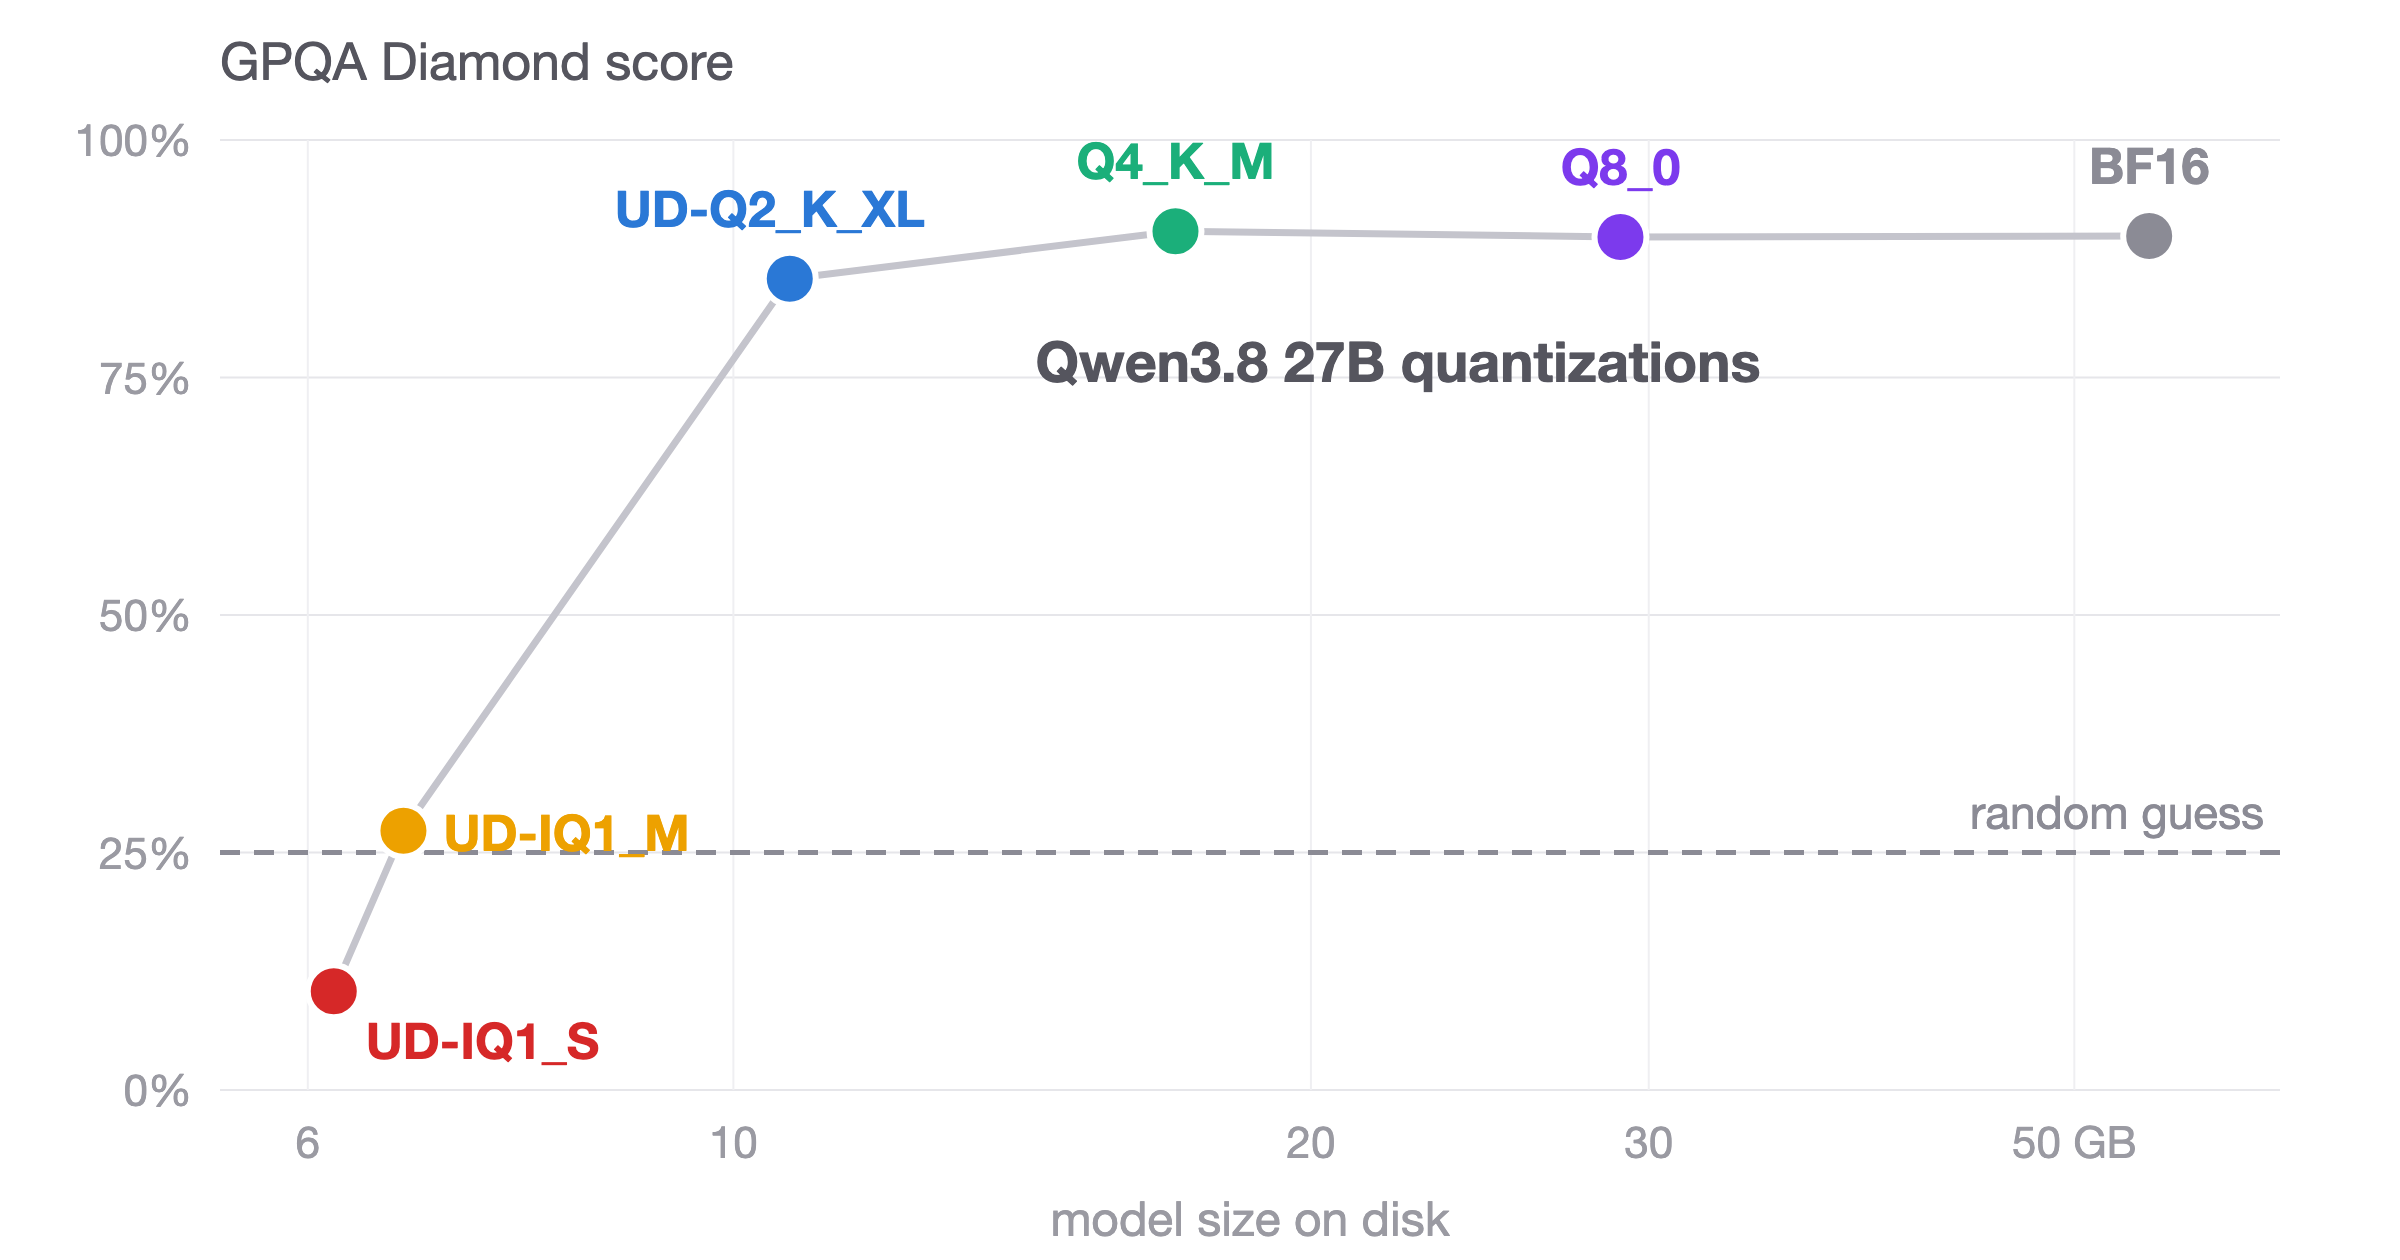
A recent benchmark evaluated Unsloth GGUF quantizations of the Qwen3.8 27B model using llama.cpp across multiple rigorous tests. The results show that the 4-bit version matches full BF16 precision while fitting on a single RTX 4090. However, extreme compression to 1-bit causes the model's performance to completely collapse.
Comments
0Discuss on Hacker NewsOnly full members can comment
Log in to express your opinion.
No comments yet.